Featured Projects
Data Engineering Projects
Stock Market Real-Time Data Engineering Pipeline — AWS
Re-engineered a Kinesis-to-Athena pipeline into an event-driven AWS architecture (EC2 → SQS → Lambda → DynamoDB/S3), buffering market ticks at 30-second intervals to overcome service limits and eliminate cold-start data loss. Built a DynamoDB state machine to detect SMA-5/SMA-20 crossovers with duplicate-alert suppression validated end-to-end via Amazon SNS. Layered a Databricks Delta Lake medallion pipeline with Auto Loader, watermark-based Silver deduplication, and Z-ORDER-optimized Gold rollups, alongside crawler-free Athena and Redshift Spectrum analytics.
Serverless Real-Time YouTube Trending ETL Pipeline — AWS
Built an EventBridge + Lambda ingestion pipeline pulling YouTube Data API v3 streams and historical 10-region datasets into an S3 Bronze layer with Hive partitioning (region/date/hour). Developed PySpark (AWS Glue) and AWS Wrangler ETL jobs to parse nested JSON, cast schemas, dedupe via window functions, and write Snappy Parquet across Bronze/Silver/Gold. Orchestrated parallel transformations with AWS Step Functions (exponential backoff), Lambda-based data-quality checks, and SNS failure alerts, serving curated Gold tables via Glue Data Catalog and Athena.
Real-Time Banking Lakehouse — Kafka, Airflow, Snowflake & dbt
Built an event-driven CDC pipeline with Debezium and Kafka capturing PostgreSQL transactions into MinIO S3 Parquet, orchestrating 1-minute micro-batch ingestion via Airflow into Snowflake VARIANT tables. Developed Silver-tier dbt staging views to parse VARIANT columns, enforce strict schemas, and dedupe transaction streams via window functions. Modeled customer/account dimensions with dbt snapshots (SCD Type 2) and open-ended sentinel dates, powering a Gold-tier Star Schema with incremental fact tables for Power BI transaction monitoring.
Retail Analytics Medallion Pipeline — Databricks, Ghost PostgreSQL & CDC
Provisioned an agentic cloud PostgreSQL database via Ghost infrastructure using VS Code MCP chat integration, establishing an automated CDC pipeline to land transactional source records directly into Databricks Bronze tables. Developed a dbt Medallion Architecture using Jinja-templated logic for a unified One Big Table (OBT) and dbt snapshots to track SCD Type 2 history. Automated daily end-to-end ELT execution using Dockerized Apache Airflow, embedding dbt freshness checks and schema tests to prevent corrupt data propagation.
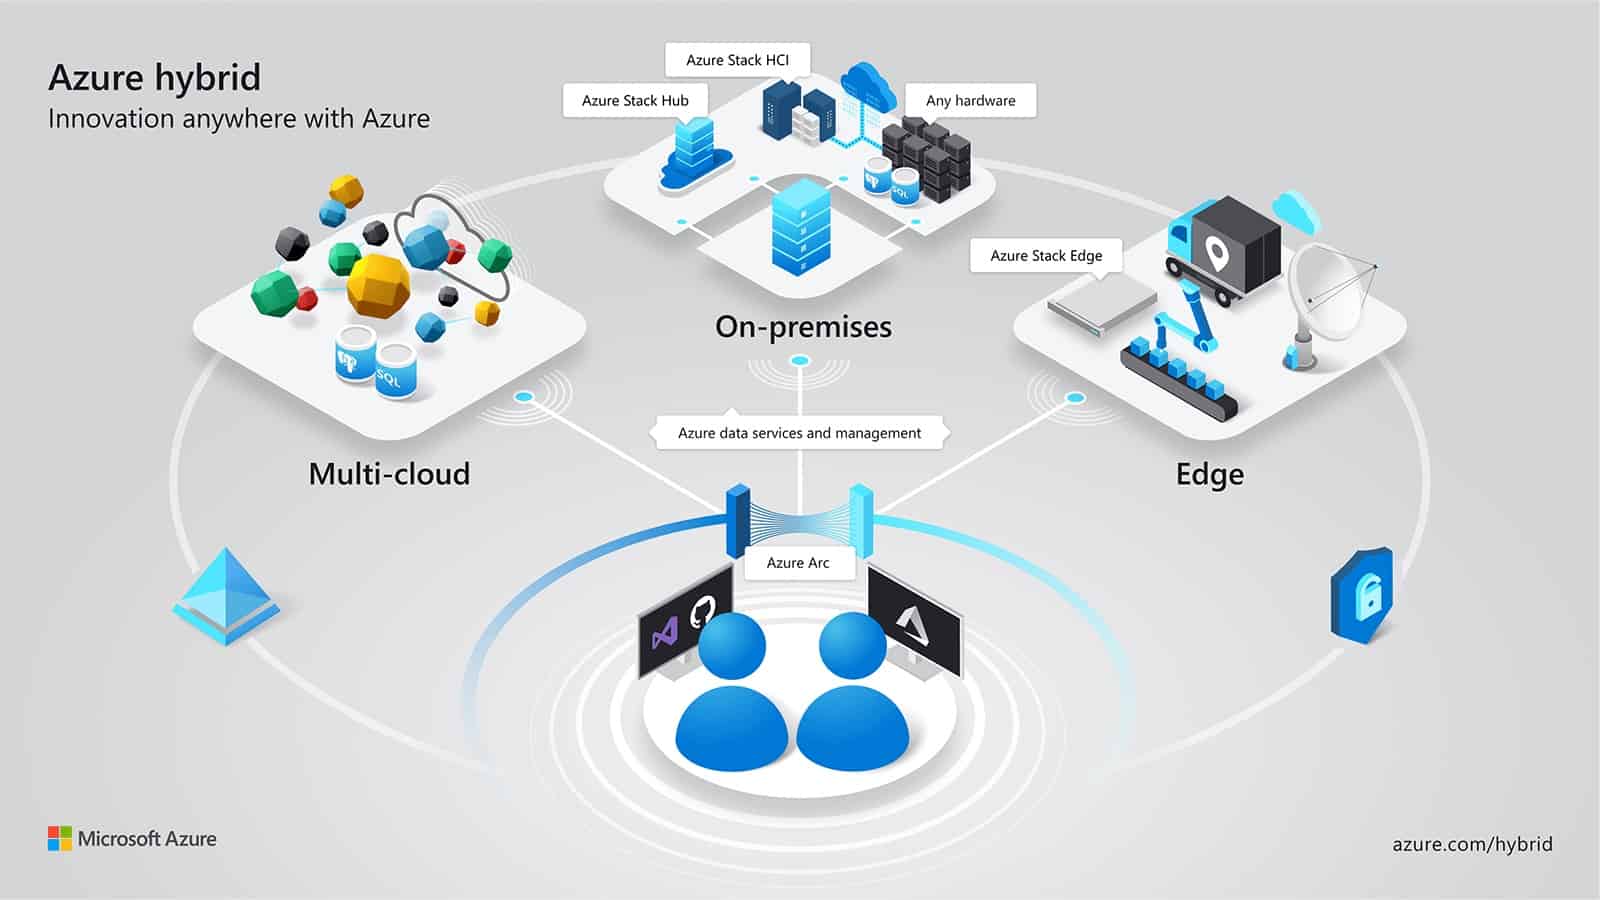
End-to-End Azure Data Analytics ETL Pipeline
Architected an Azure ETL/ELT pipeline using Azure Data Factory with a Self-Hosted Integration Runtime to ingest on-premises data into ADLS Gen2, running scalable PySpark transformations on Azure Databricks. Enforced governance and security via Unity Catalog and Azure Key Vault, built optimized relational schemas in Azure Synapse Analytics to power real-time sales KPI dashboards in Power BI. Automated pipeline monitoring and real-time failure alerts using Azure Monitor and Logic Apps, managing codebase lifecycles through Git branching.
Movie Ratings Cloud Data Warehouse — Snowflake, dbt & AWS S3
Architected an ELT pipeline staging 32M rows in AWS S3, loading raw data directly into Snowflake Bronze tables via external stages and bulk COPY execution. Built a dbt Medallion Architecture using watermark-based incremental Silver tables and dbt snapshots (SCD Type 2) to track historical changes across core entities. Implemented a Jinja2-templated framework in dbt to dynamically build a Gold-tier One Big Table, integrating pre-aggregated tag arrays and ephemeral marts. Delivered dual serving layers — serverless Amazon Athena over S3, and Tableau over Snowflake — for interactive rating trend dashboards.
Spotify End-to-End Azure Data Engineering Pipeline
Enterprise-grade Bronze/Silver/Gold Medallion data lake using Azure Data Factory and ADLS Gen2. Engineered a parameterised CDC incremental ingestion framework with Lookup/ForEach watermark tracking. Implemented Spark Structured Streaming with Databricks Auto Loader for schema-evolving ingestion with SCD Type 1/2 dimensional modelling. Built a Jinja2-templated SQL framework for dynamic Star Schema construction in Unity Catalog — replacing hand-written SQL with config-driven query generation. Multi-environment CI/CD via Databricks Asset Bundles and Azure Logic Apps.
Data Science & ML Projects
AI Document Chatbot — Hybrid RAG System
Production-grade AI chatbot with hybrid BM25 sparse search + dense HuggingFace embeddings + cross-encoder re-ranking, achieving 85% context-aware accuracy on 100+ page PDFs. Features LLM-as-a-Judge evaluation framework and stateful query routing via LangGraph. Scaled to Azure-native enterprise variant using AzureChatOpenAI and Document Intelligence.
Depression Tweet Detection — LSTM NLP
End-to-end NLP pipeline on 10K+ social media posts using TF-IDF, Word2Vec, and an LSTM network — boosting classification accuracy from a 90.7% Naive Bayes baseline to 99.65% accuracy. Refactored into a modular Python package with pytest test suite and GitHub Actions CI/CD pipeline.
Wind Power Forecasting — LSTM Deep Learning
Comprehensive EDA with Time-Series Decomposition (Trend/Seasonality/Residual) on wind-power datasets. Developed LSTM (Keras/TensorFlow) and Holt-Winters models achieving 85% forecasting accuracy, validated via heatmaps, scatterplots, and ADF/ANOVA hypothesis testing. Kaggle notebook earned 33+ community votes.
Employee Attrition — PySpark MLlib
Scalable ETL and feature engineering pipeline using PySpark (Spark SQL) to process multi-feature employee tabular datasets. Applied cross-validation and hyperparameter tuning with PySpark MLlib classification models achieving 87% accuracy in identifying key attrition drivers.
Retail Analytics — RFM & Customer Segmentation
Customer segmentation using K-Means (elbow method, silhouette analysis) and DBSCAN clustering on RFM features. Identified 3 clusters where the top 40% segment generated 60% of revenue, validated with A/B testing achieving 18% higher engagement.
End-to-End Uber Trips Data Analysis
Rigorous statistical analysis (T-Tests, ANOVA, ADF) on 6 months of Uber trip data. Eliminated 25% data redundancy via Excel preprocessing; built interactive Power BI (DAX) and ggplot dashboards accelerating executive reporting by 30%. Forecasted 6-month trip demand using ARIMA, SARIMA, SARIMAX, Exponential Smoothing, and Prophet — evaluated via MAPE/RMSE.
Air Quality Forecasting — TFT (PyTorch)
End-to-end multivariate time-series pipeline using PyTorch and PyTorch Lightning — integrating EDA, hyperparameter tuning via LR finder, and cross-validation to build a Temporal Fusion Transformer (TFT) forecasting PM2.5 air quality across a 365-day horizon. Achieved 40.9% SMAPE — 25% improvement over the naive baseline.
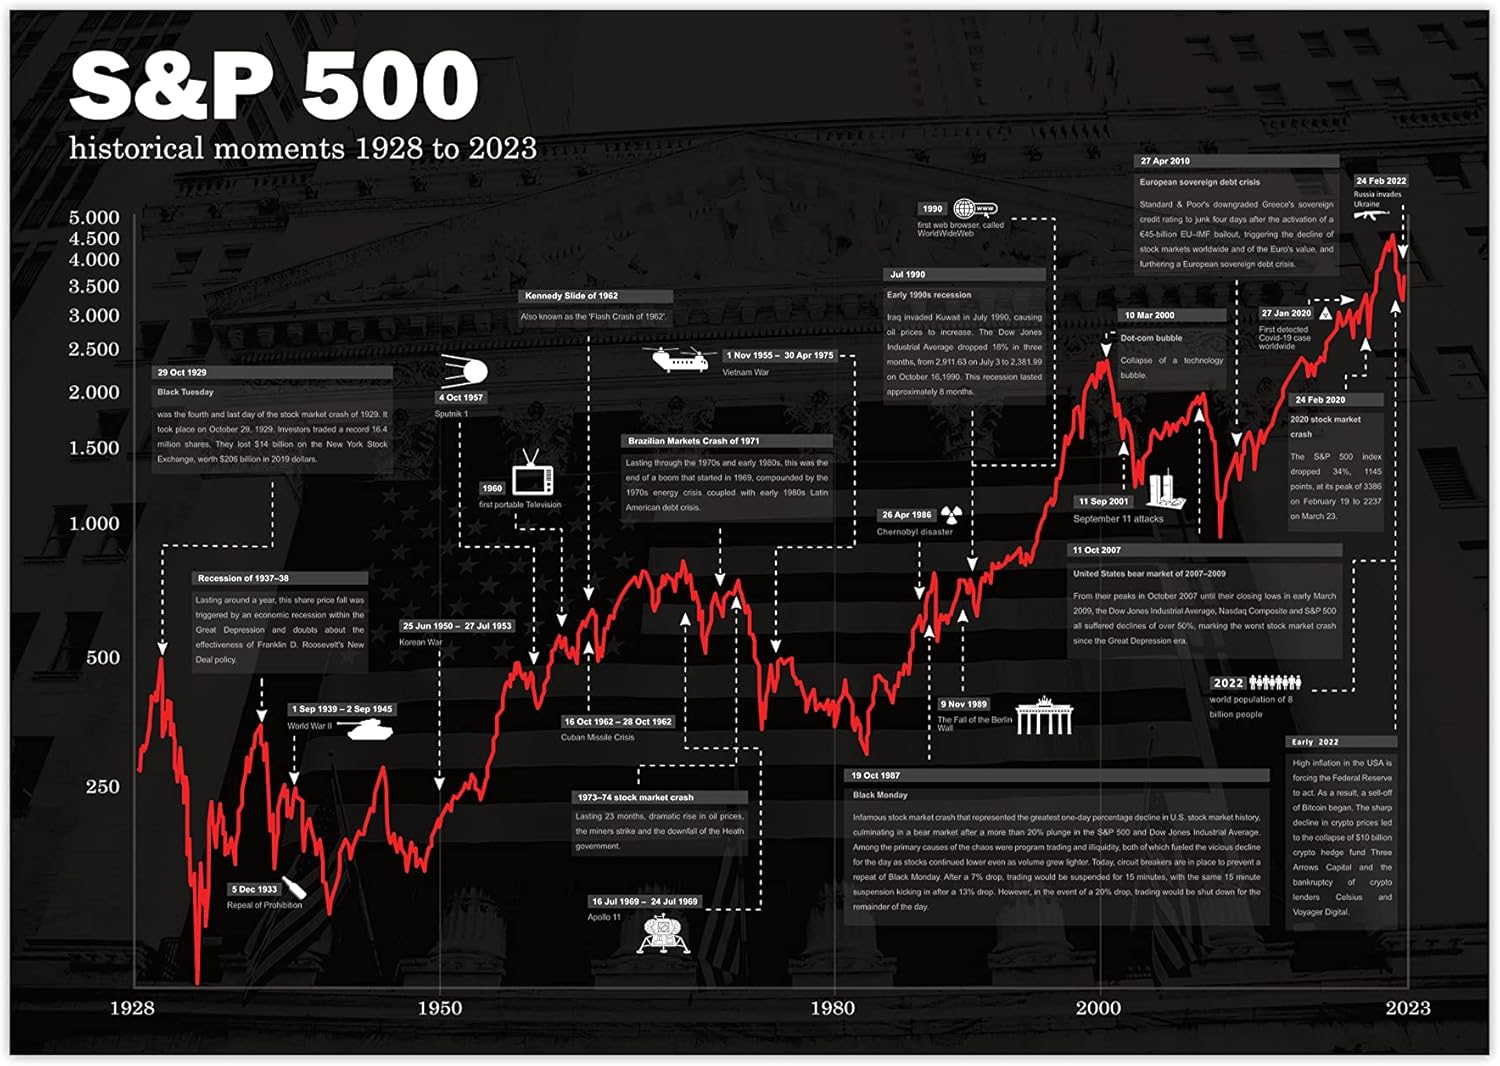
S&P 500 Return Forecasting — PyTorch LSTM & Model Benchmarking
End-to-end Azure Databricks ML pipeline with a Delta Lake feature store engineered using PySpark window functions — 15+ technical indicators, ADF/KPSS stationarity testing, STL decomposition, and cross-ticker correlation heatmaps. Designed a PyTorch LSTM with parent-child transfer learning (partial layer unfreezing, Huber loss, L2 decay) and Optuna hyperparameter optimisation. Walk-forward CV across 10 tickers with MLflow experiment tracking and backtesting against buy-and-hold benchmark.
Airline Loyalty Churn Prediction — End-to-End Azure MLOps
Production MLOps pipeline on Microsoft Azure following Medallion Architecture (Bronze → Silver → Gold Delta Lake). Engineered 15+ behavioural features with parameterised snapshot date to eliminate temporal data leakage. Trained XGBoost with SMOTE within CV folds for 12% class imbalance — achieving 0.967 ROC-AUC and 0.879 F1-score (+28.4% over logistic baseline and Azure AutoML). Componentised pipeline with automated quality gate deployed as Azure ML Batch Endpoint.
Software Engineering & Agentic AI Projects
Brunch Express — Food Delivery Backend
Production-ready Spring Boot 3.3 backend containerised with Docker and orchestrated via Kubernetes. Secured with Spring Security (JWT + RBAC), stateless data-access boundaries, and CORS policies. Features CI/CD pipeline automation, Global Exception Handling via @RestControllerAdvice, and a real-time analytics engine with Spring Data JPA tracking revenue and order transitions.
Expense Tracker — MCP Server (Agentic AI)
FastMCP expense tracking API with SQLite backend built using the Model Context Protocol (MCP) — enabling Claude AI to directly interact with financial data via structured tool calls. Handles 10+ categories with full CRUD operations, budget analytics, and MCP protocol compliance for seamless AI agent integration.